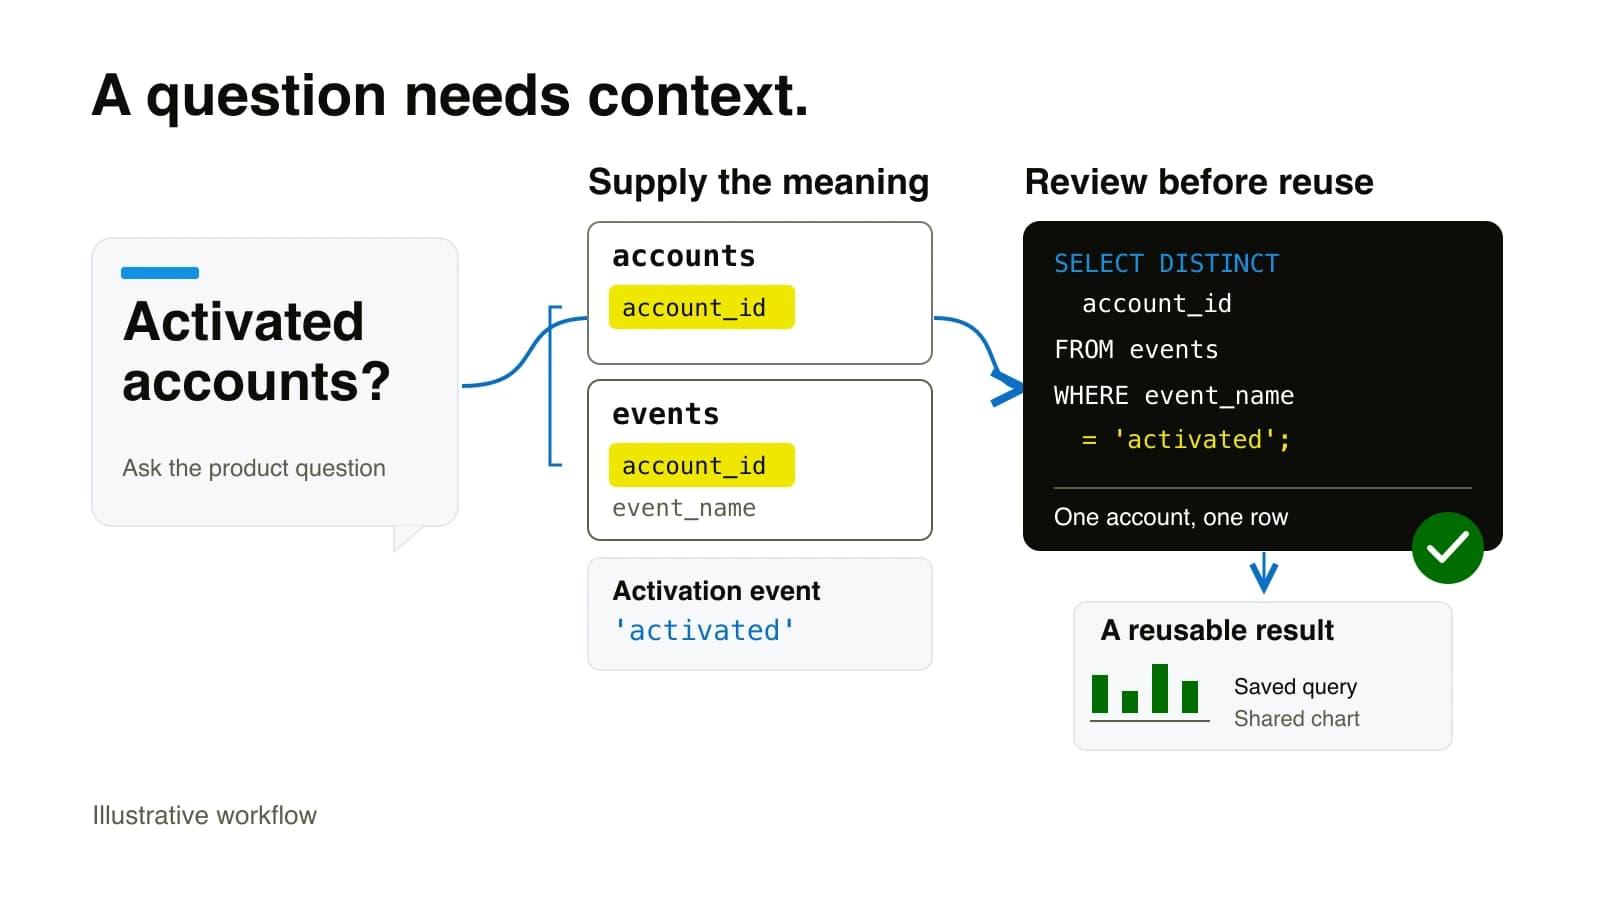
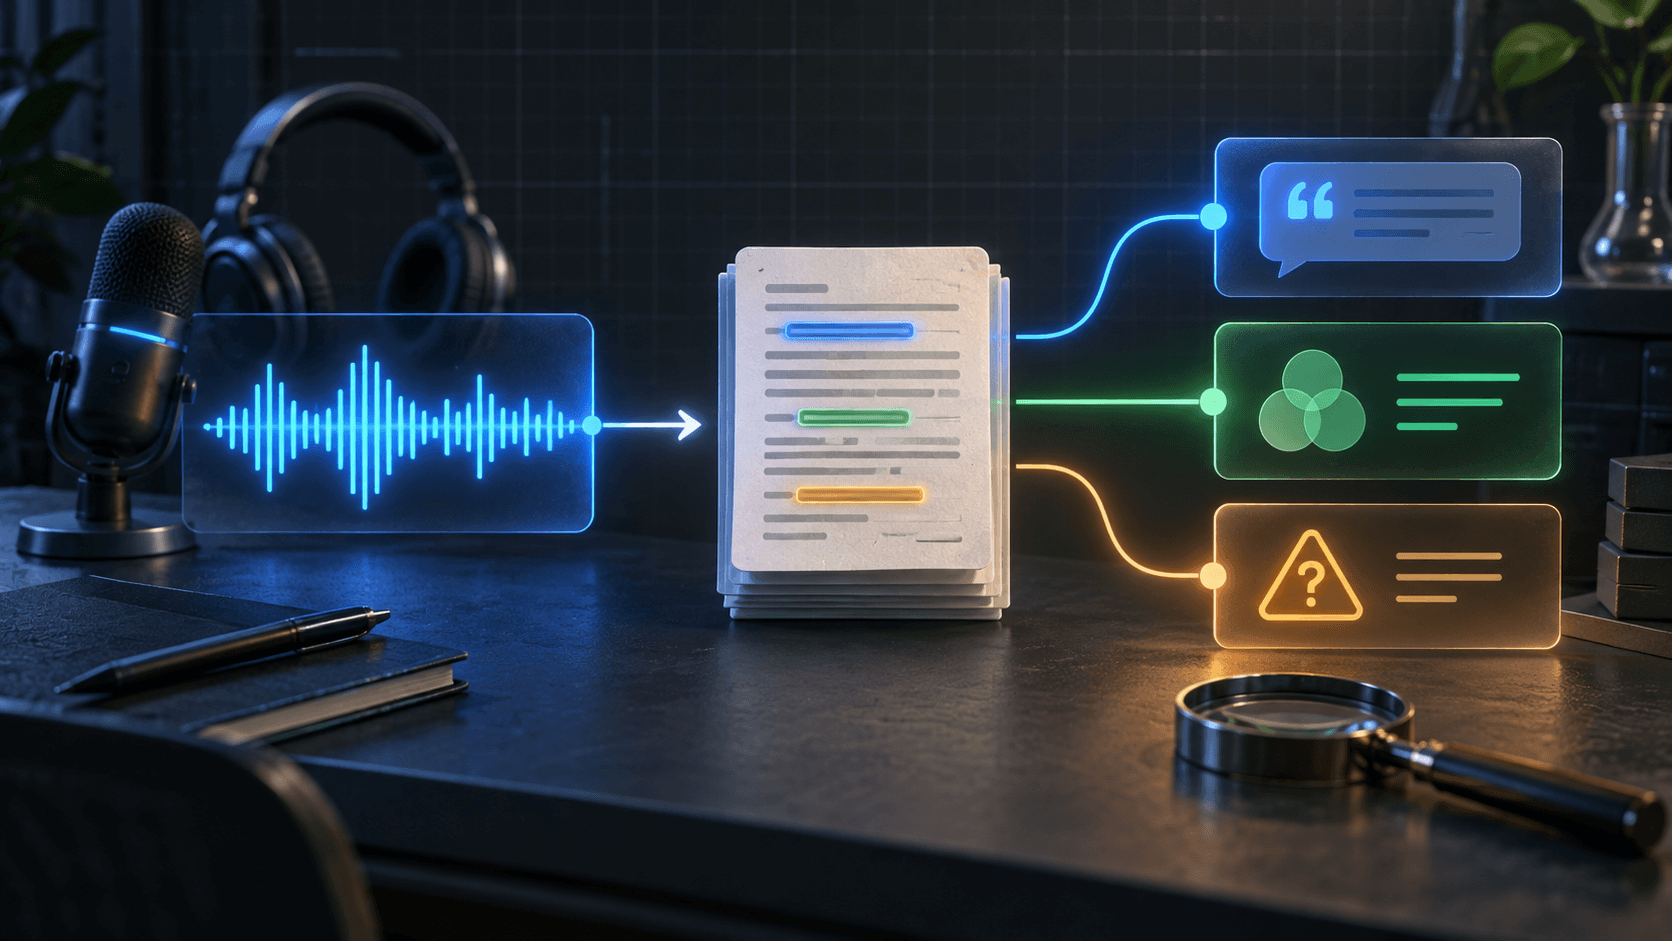
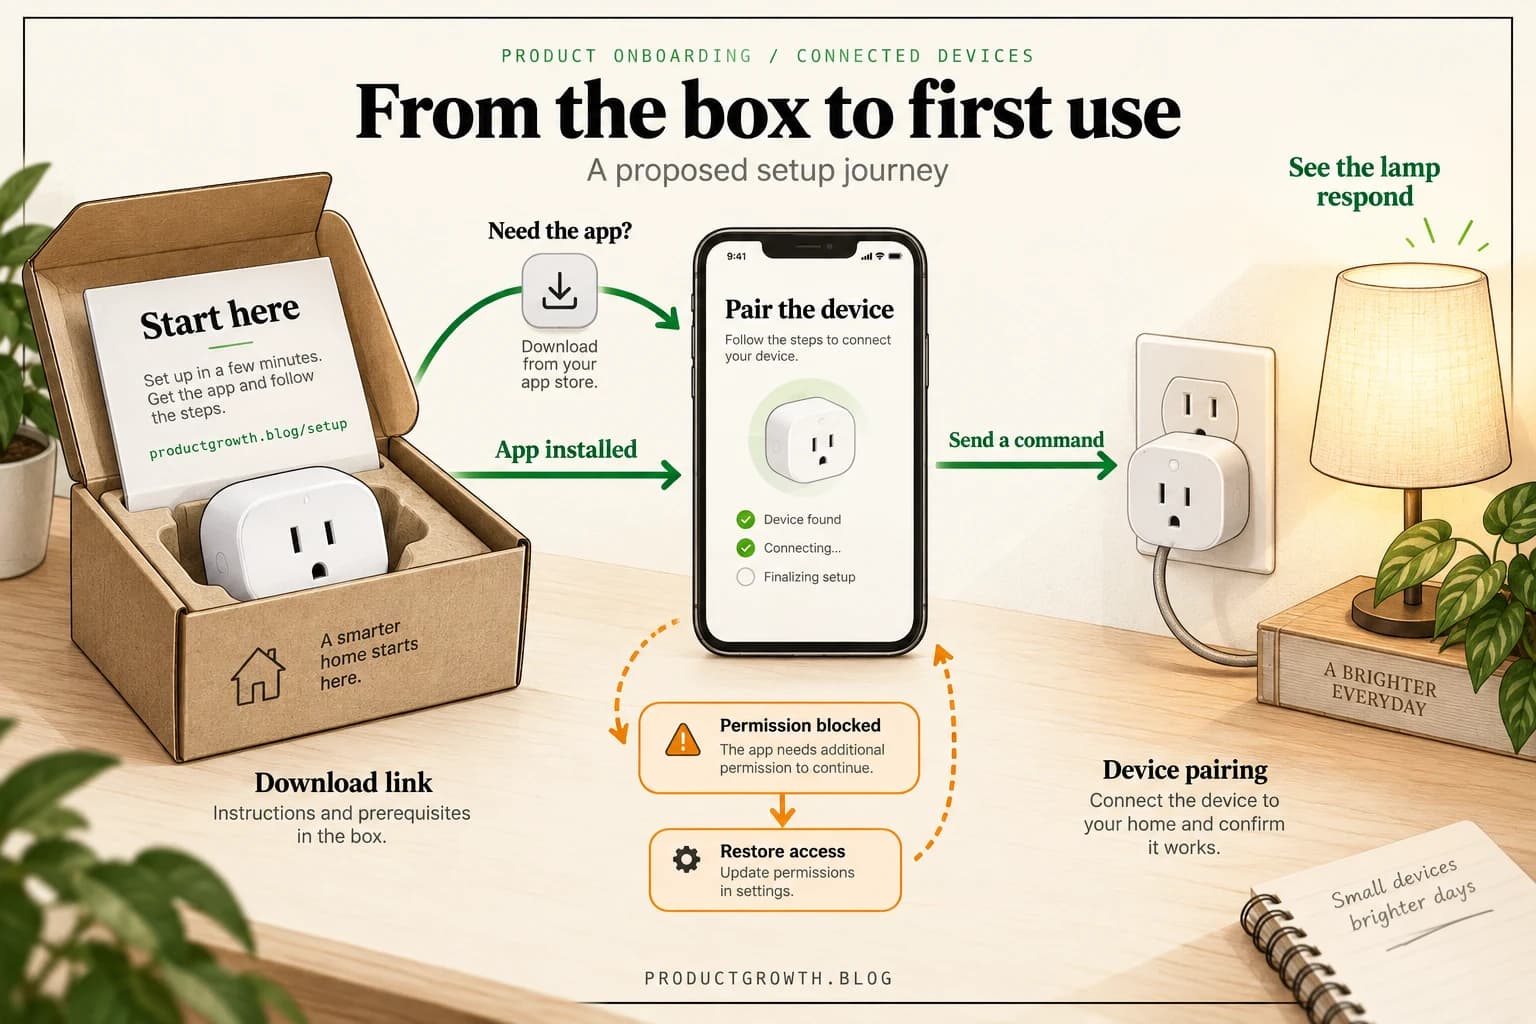
PostHog can put an unusual amount of a product team’s daily work in one place. A product manager can inspect an activation funnel, open a recording of a person who dropped out, ask an engineer to put a fix behind a feature flag, and read the experiment against the same event vocabulary. That sequence is the attraction. It is also where a bad implementation becomes expensive: a shared stack spreads weak event names, missing consent, and confused identity rules across more decisions.
The useful question for a product team is whether one shared context across analytics, replay, release control, experimentation, and warehouse queries improves the decisions it makes each week. The answer depends on its event definitions, access controls, and usage costs.
Section 01PostHog: one workspace for the product question and the release
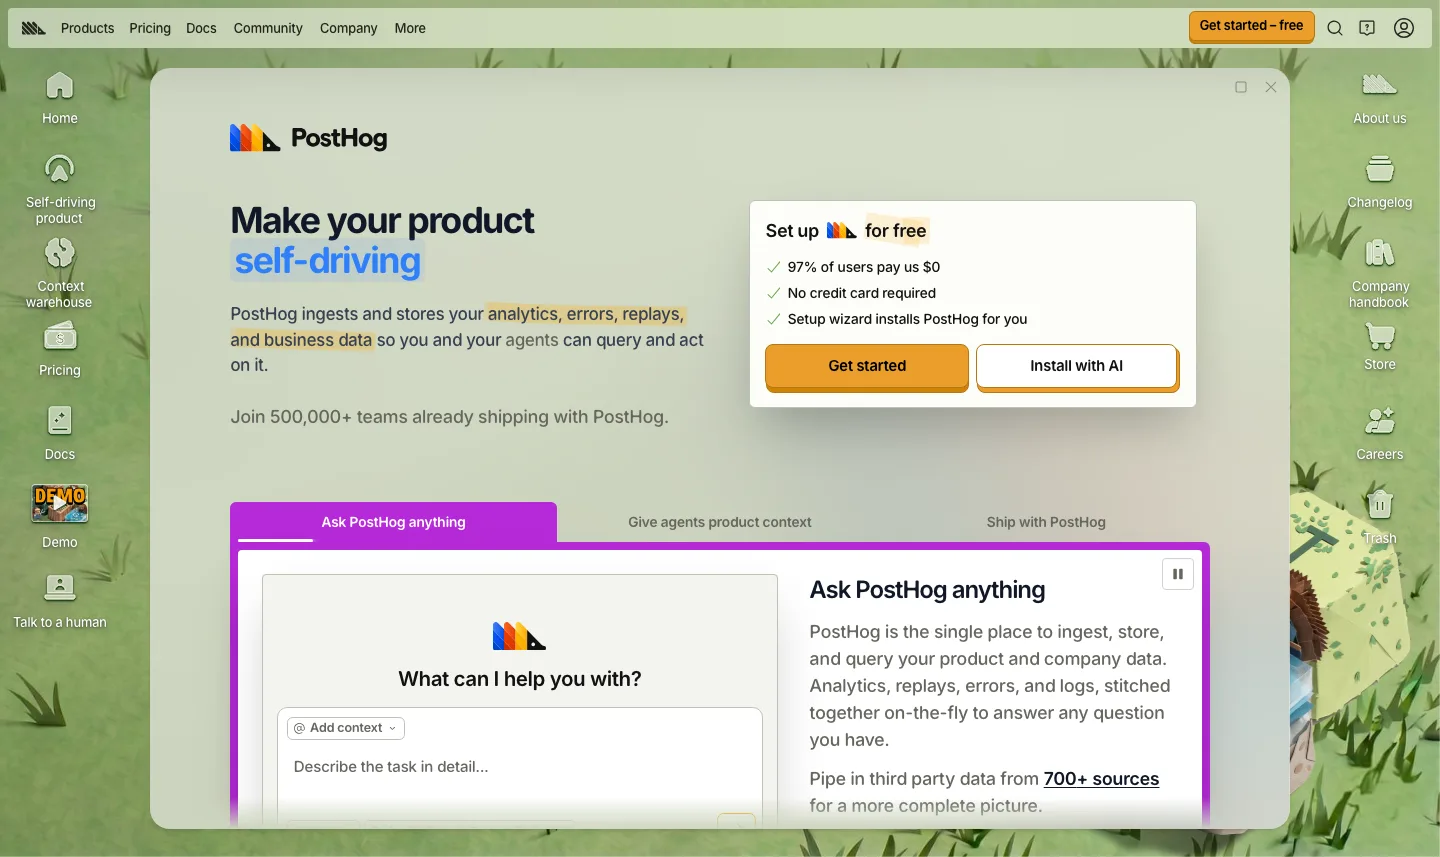
PostHog now describes a broad product family rather than a single analytics dashboard. Its product overview groups product analytics and replay with feature flags, experiments, a context warehouse, surveys, and newer developer tools. For this review, the purchase decision stays narrower: can five connected jobs replace a hand-built chain of event collection, replay search, release toggles, test reporting, and warehouse joins? A buyer who only needs one of those jobs should price that job first, because breadth itself has no measurable payoff.
For a product team with engineering support, the strongest case is the short path between a suspicious funnel step and the sessions behind it. The trade-off is that one stack also concentrates the consequences of weak event definitions, unclear access, and messy warehouse joins. Judge fit through the connected workflow, analytical depth, operations, cost, and day-to-day ease of use.
| Work the team needs to do | PostHog capability | What the pilot must verify |
|---|---|---|
| Find an activation drop-off | Events, funnels, paths, retention, cohorts, and SQL insights | Whether the same identities and event definitions survive browser and backend steps |
| See what a stuck person did | Session replay linked to event and funnel context | Recording coverage, masking, consent, and safe access to recordings |
| Release a candidate fix | Feature flags with targeting and percentage rollout | Stable flag exposure, fallback behavior, and rollback ownership |
| Test the fix | Experiments connected to flags and selected outcomes | Exposure, sample size, outcome definition, and decision rules |
| Join product and business data | Imported sources and SQL in a shared warehouse context | Connector coverage, freshness, join keys, and metric ownership |
Section 02The integrated path is useful only when the same question survives each handoff
Imagine an onboarding team sees fewer new accounts create their first project. In a disconnected stack, an analyst may define a funnel in one tool, ask another team for recordings, paste user IDs between systems, then ask an engineer to create a rollout in a third place. Each handoff can change the population. The analyst may inspect all signup sessions while the funnel counted only mobile visitors on a particular plan. The result feels like a coherent diagnosis but answers a different question.
PostHog’s product analytics page says a funnel point can open related recordings, and its replay material describes events, people, and flag context attached to sessions. That is a meaningful product design choice. It reduces the manual work of finding the same population across tools, provided identity and session stitching are correct. A recording can show a button below the fold or an error at a decisive moment. It still cannot tell you whether that moment caused the aggregate drop. You need the denominator, a comparison group, and sometimes a direct conversation with the user.
This distinction matters because a single workspace can make a weak inference feel unusually persuasive. A replay is vivid. If the funnel only contains identified users, if recording sampled a small subset, or if a backend success event arrived late, the visible person may not represent the loss in the chart. The first pilot should therefore trace one account across the raw event list, the funnel, the recording, and the flag exposure. If the IDs disagree, fix the instrumentation before expanding the tool.
Section 03Product analytics: fast exploration still needs a careful event plan
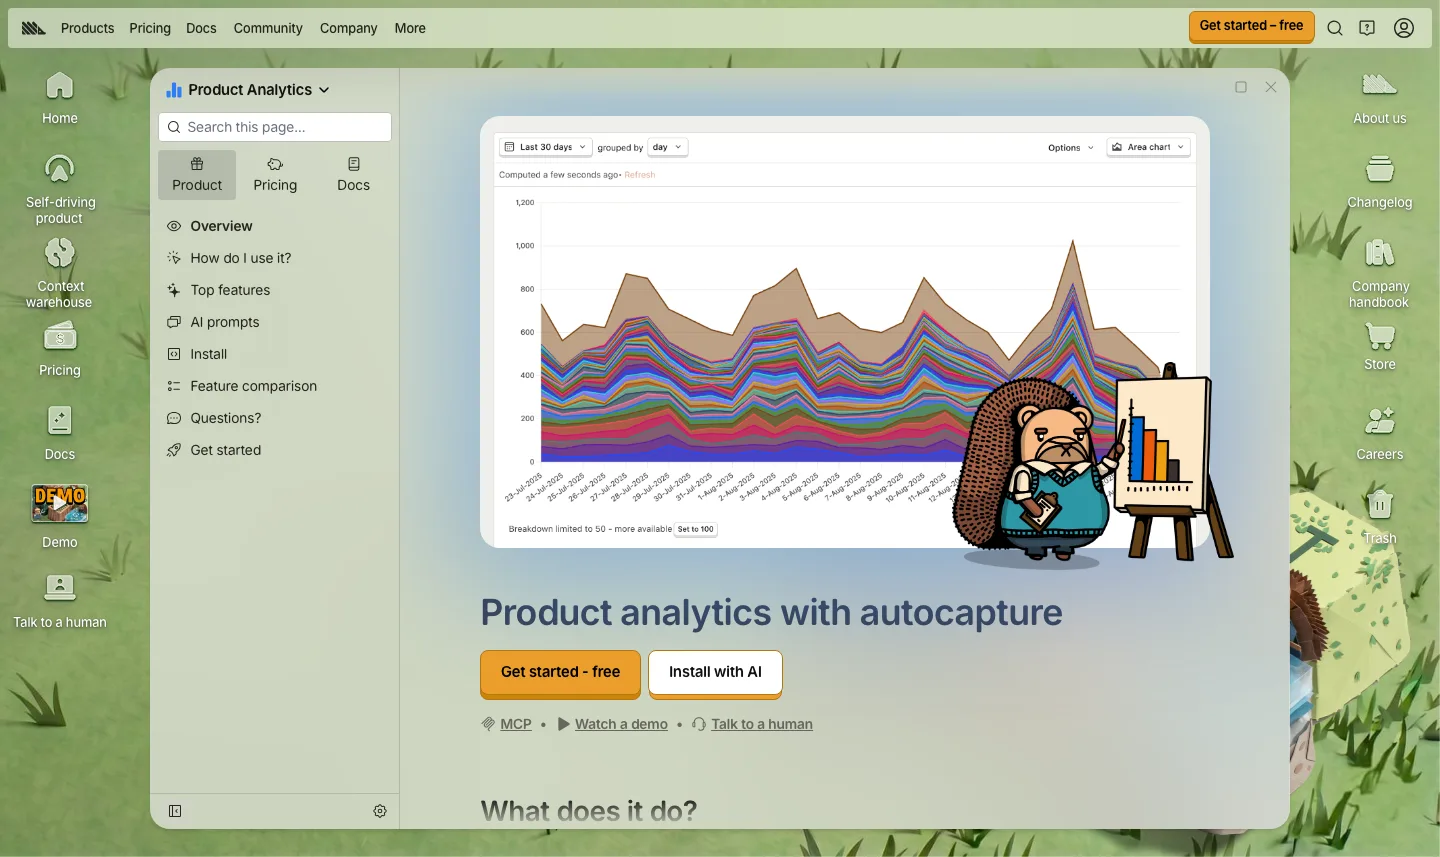
The analytics surface covers the usual product questions: trends for usage, funnels for ordered steps, retention for return behavior, paths for navigation, and SQL for questions the visual builders cannot express. PostHog says web autocapture can collect pageviews, clicks, and form submissions after installation. Custom events are still the right choice for business actions such as `project_created`, `invite_accepted`, or `first_report_exported`. An anonymous click on a div is a starting clue, not a durable definition of activation.
The funnel documentation makes the measurement choices visible. A funnel can use sequential, strict, or any-order steps; filter event, person, or group properties; and show overall or step-relative conversion. Those settings change the answer. If you count an optional email verification as a required step, the funnel can understate completion. If you use person properties before identifying people, the segment may disappear. A PM needs to write the population, success event, and conversion window beside each consequential chart.
Autocapture helps answer an unplanned question about a click path without waiting for a release. It also creates noise. A changed button label or CSS structure can make a loosely defined action fragile. Before a team uses PostHog for a board metric, it should instrument a named event from the application’s business logic, keep a versioned definition, and test it on web and backend paths. Use autocaptured events to explore friction, then promote the few actions that matter into stable product events. That is more work than a slogan about automatic analytics suggests, but it keeps future comparisons interpretable.
PostHog’s SQL path can be useful when PMs and analysts need a cohort that spans several tables. It also shifts work toward people comfortable reading query logic. In an older Product Management discussion, one commenter said PostHog was too complicated for their use cases, while another preferred some Amplitude analytics views despite liking PostHog’s integration. Those dated, self-selected accounts suggest a pilot question rather than a general weakness: can your nontechnical owner reproduce the three recurring reports without a specialist?
Section 04Session replay: a good clue can still be an unsafe recording
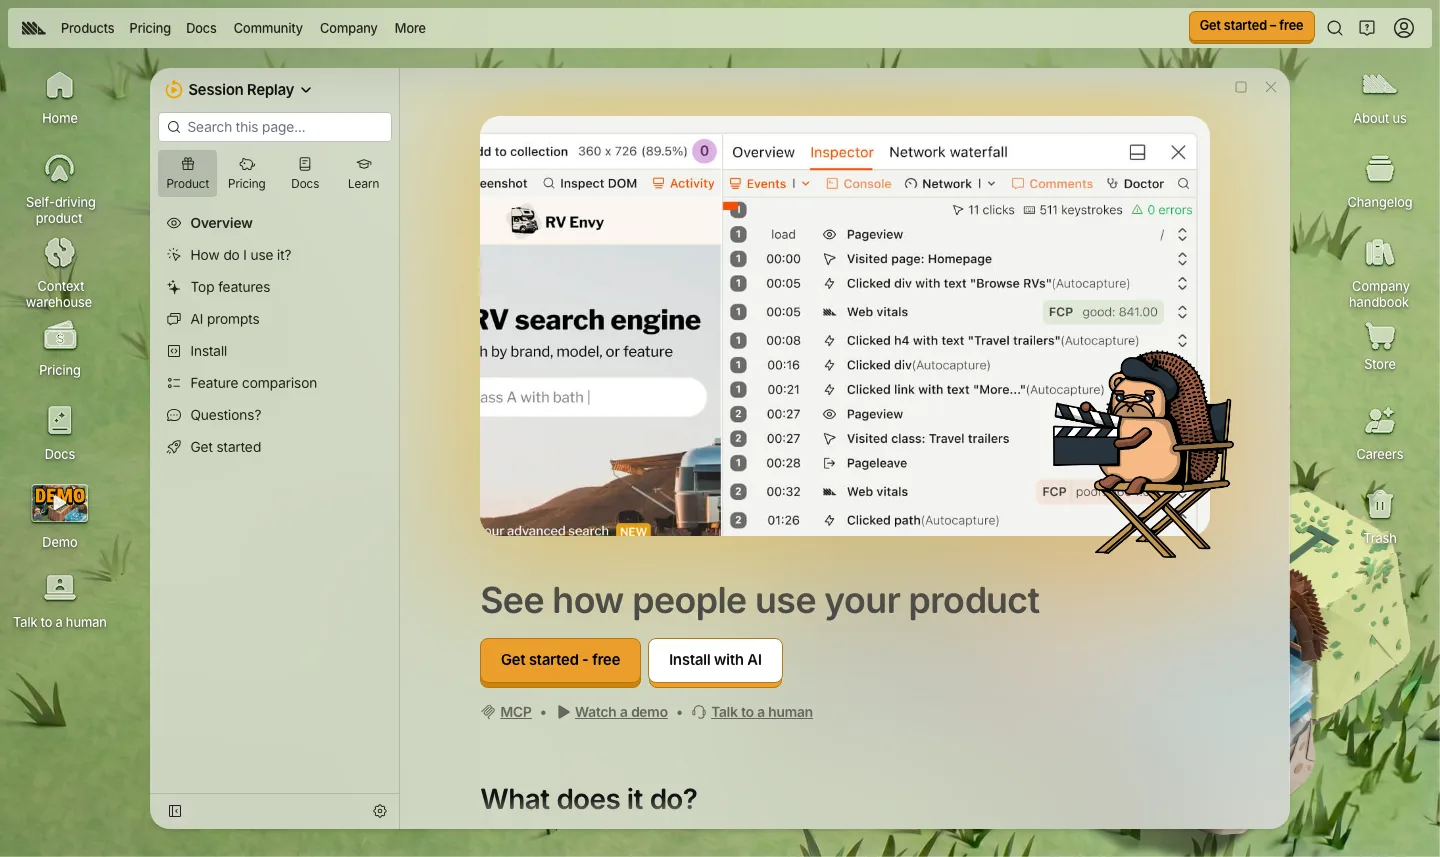
Replay gives the quantitative chart a route back to a person’s experience. PostHog shows a recording alongside browser activity, and its replay documentation describes jumping from a funnel drop-off or an exception to relevant sessions. The same documentation says teams can sample recordings, gate them by URL or flag, and mask text, inputs, and whole elements before capture. These controls make a focused investigation possible without recording every screen by default.
The useful question is narrow: what happened for people who entered this funnel step but did not finish? A product team can watch a small, preselected set of recordings, note repeated visible symptoms, then return to event counts or user interviews to test whether the symptom is widespread. Watching random sessions for an afternoon produces memorable anecdotes and often no decision. A replay can reveal a disabled button, a confusing form state, or a failed network request. It cannot read intent, prove causation, or substitute for accessibility testing.
Privacy is the purchase gate here. A masked input can sit beside sensitive rendered text, a support agent may see a session they should not, and a consent choice may change which sessions exist. PostHog’s privacy guide assigns the customer responsibility for what to collect and how to communicate it to users. During a pilot, walk through the actual screens that contain names, payments, health details, or customer records. Inspect the stored replay as a permitted reviewer and a restricted reviewer. Verify masking, collection rules, region, access, deletion, and retention with the people responsible for privacy.
Replay coverage also changes the evidence available to the PM. If the team samples recordings or blocks sensitive routes, the absence of a replay does not mean the event was false. Document which users and pages could be recorded. Keep the aggregate chart as the count and the replay as an explanation candidate. The pricing page currently gives the free plan 5,000 recordings each month, with replay retention of one month on Free and 90 days on pay-as-you-go. A long sales cycle or delayed incident review may require a different retention arrangement.
Section 05Feature flags: release control is a production responsibility
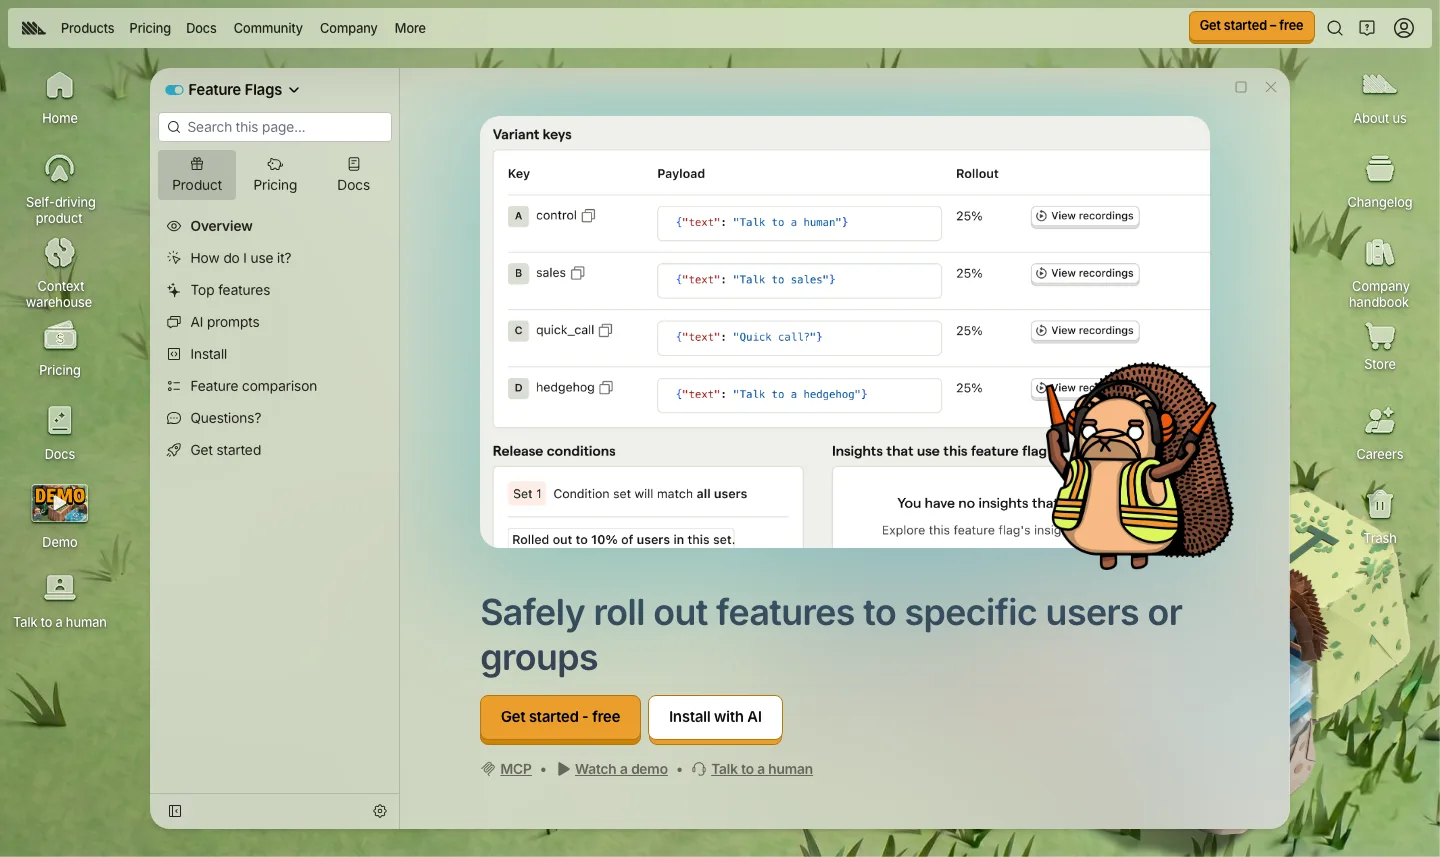
Feature flags separate deploying code from showing it to everyone. PostHog’s feature flag page describes percentage rollouts and targeting. That fits an onboarding fix: an engineer can ship a change hidden behind a flag, expose it to internal accounts, then expand to a small eligible population while watching a guardrail such as error rate. If the guardrail moves badly, the team can turn exposure down. This is useful release control, but it does not undo data migrations, queued jobs, or side effects already triggered by the new code.
A flag belongs in a release plan with an owner, default state, rollback condition, and removal date. If the client loads a flag after rendering, users may see a brief wrong state; if a server evaluates it without the needed person properties, targeting may fail or fall back. PostHog documents server-side local evaluation for supported SDKs, with a secret key and a cache of flag definitions. It warns that cold starts, missing properties, and fallback behavior need explicit handling. That documentation is evidence of an implementation option, not evidence that the option will work in your architecture.
Flags can be expensive to reason about once they overlap. A person might qualify for an account-level rollout, a user-level experiment, and a support override at the same time. Define precedence and log the actual exposure event the experiment will use. Test a returning identified user, an anonymous browser, a newly invited teammate, and an account that changes plan. The practical goal is simple: two engineers should be able to explain who saw the feature and why. If they cannot, adding more flags will make the release state harder to audit.
Section 06Experiments: a connected flag does not create a valid test
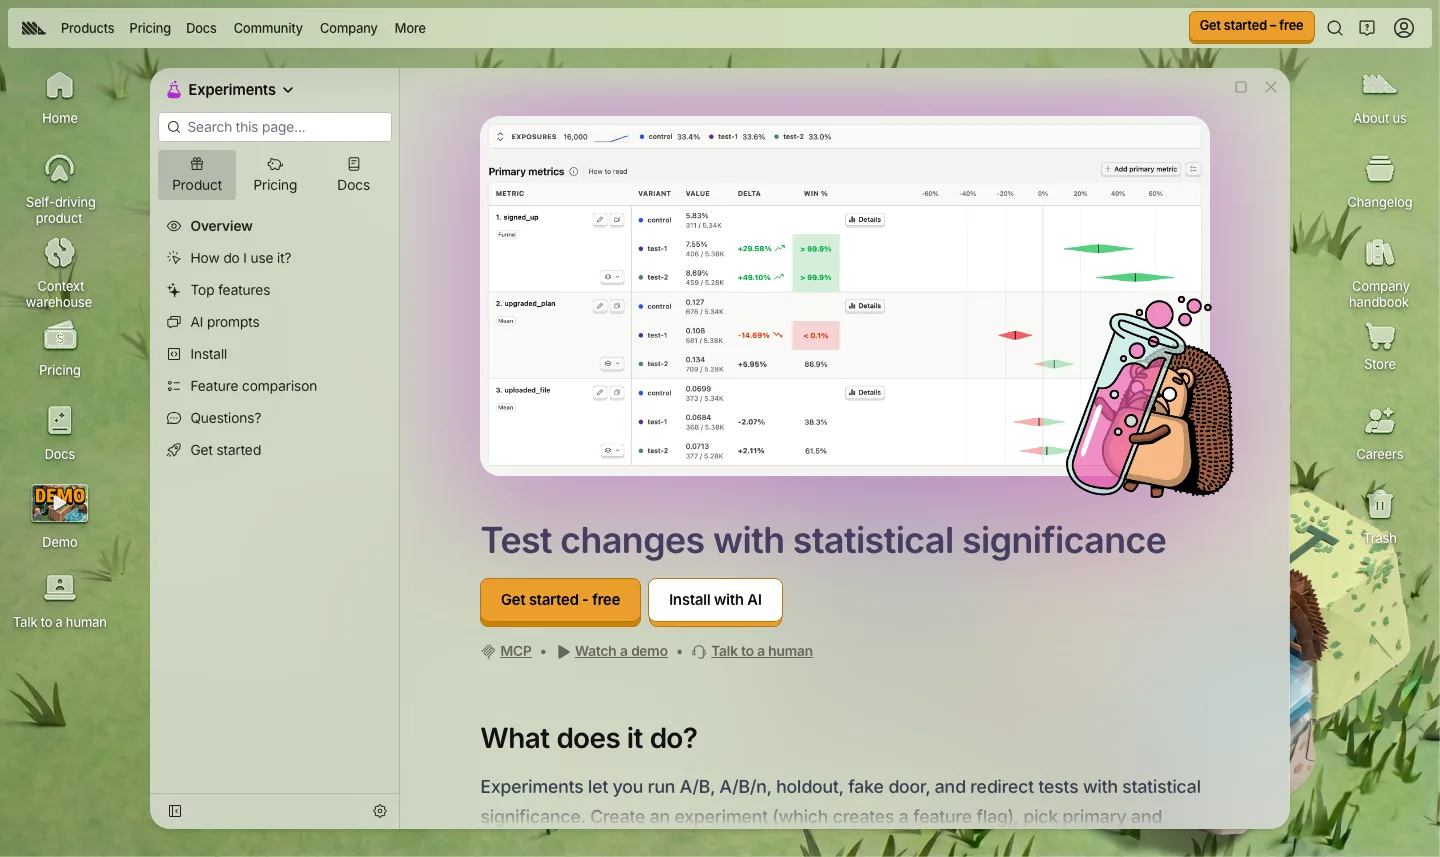
PostHog’s experiments product sits beside its feature flags. This can shorten the path from a controlled rollout to a test with defined outcomes. It is useful when the same team owns the change, exposure, and primary metric. For an onboarding test, the primary metric might be the share of eligible new accounts that create a first project within seven days. A guardrail could be errors on the creation route. Write both before looking at a result, and decide which users are eligible before the first exposure.
A flag is only the delivery mechanism. The experiment is credible when assignment is stable, each person is counted in the right variant, exposure means the person actually could see the change, and the outcome window fits the behavior. A UI that reports a probability or interval cannot repair a missing exposure event. Nor does a positive seven-day result say anything by itself about a 90-day retention rate. Product leaders should ask an analyst to inspect the raw exposure and outcome event counts before accepting a dashboard verdict.
This is also where the integrated stack has a genuine potential advantage: the release owner and analyst can share event definitions without exporting rows to another system. The potential remains conditional. If the product team sends experiments to a warehouse for official reporting, the cohort, user identity, time zone, and exclusion logic need to match there too. Keep the test plan in a document outside the dashboard so a later reader can distinguish the prespecified question from the segments explored after the result arrived.
Section 07The warehouse expands the question, and the governance work
A product event often needs business context. The PM wants to know whether invited accounts later paid, whether a billing plan changed before churn, or whether a support case explains a sudden dip. PostHog’s context warehouse page says it can import third-party sources and query them alongside product data. That makes the integrated story more useful than a funnel alone: `first_project_created` can be related to an account record or invoice without switching to a separate BI tool for every question.
Do not read “one place” as a guarantee of one correct number. A warehouse join depends on stable account IDs, source freshness, duplicate handling, and shared metric definitions. If a Stripe subscription is updated at noon while a PostHog event arrives seconds after signup, a same-hour conversion chart can tell a different story from the finance report. A serious pilot should select one business question, list each source table, identify the join key, check the latest sync time, and reconcile a small set of rows with the system of record. If that takes several days, the problem is the data contract, not necessarily the query editor.
A team with an established warehouse can still use PostHog for discovery and export only the few approved events needed for official reporting. Consolidation does not require deleting a trusted finance model. Conversely, a small team without a warehouse may value being able to query product and billing data together sooner. The choice depends on who owns the definitions and whether that person can spot a stale connector.
Section 08Pricing: model four meters, not one “free plan”
PostHog’s pricing page lists separate monthly free allowances. As checked on 25 September 2026, they are one million analytics events, 5,000 session recordings, one million feature flag requests, and one million warehouse rows. Experiments are billed with feature flags. The page also lists a free project with one year of event and metadata retention, while pay-as-you-go allows six projects and seven-year event and metadata retention. Replay retention has its own shorter limits. Use your event and request counts to estimate cost, and recheck live plan terms before buying.
| Meter | Public monthly free allowance | Forecast from your own product |
|---|---|---|
| Product Analytics | 1 million events | Count page and custom events per active user, plus backend duplicates and autocapture. |
| Session Replay | 5,000 recordings | Estimate eligible sessions after consent, route rules, and sampling. |
| Feature Flags and Experiments | 1 million billable flag requests; experiments billed with flags | Measure billable requests across web and server SDKs; account for refreshes, caching, and local evaluation. |
| Context warehouse | 1 million rows | Estimate rows imported or synced from each source and their update pattern. |
A team can stay free for analytics and pass the replay limit, or have modest replay but a high-volume flag evaluation path. Add a card and the extra usage is billed by product. Without one, the pricing page says usage stops at the free limit. This is a useful protection against a surprise invoice, but a stopped meter can remove a signal just when the team needs it. PostHog says paid users can set billing limits per product. An owner should set and test those limits, then decide what the product should do if a flag request or replay budget is constrained.
The right forecast starts with a week of representative traffic, not a vendor calculator filled with guessed monthly active users. Count actual events by name, find the noisiest autocaptured actions, estimate recordings by route and consent state, inspect flag requests from both web and server SDKs, and list row sync frequency for warehouse sources. Then model a normal month and a peak month. A 2025 Product Management pricing thread includes a user warning that teams can underestimate event counts. Count real events for a representative week before choosing a plan.
Self-hosting is a separate operating choice. PostHog’s open-source comparison describes a Docker Compose release for small deployments and says it recommends Cloud above roughly 300,000 events a month because scaling becomes complex. That is PostHog’s operating guidance rather than a fixed plan cap. A team considering self-hosting for privacy or budget should cost the engineer time, upgrades, storage, backups, and incident response along with the invoice it hopes to avoid.
Section 09What product teams report after adoption
The public feedback points in two directions. A July 2026 G2 review on PostHog’s seller page describes a team moving from an onboarding funnel to sessions for the affected segment. That account closely matches PostHog’s documented workflow and gives a concrete example of why integration matters. The review is marked as incentivized. Use it as one example of the workflow to reproduce with your own events.
A 2024 Reddit discussion among product managers contains one user who liked PostHog’s integration while preferring Amplitude for some analytics views. Another said PostHog was too complicated for their use cases. A separate commenter raised SSO as a security procurement concern. Product interfaces and packages may have changed since those comments. The decision value is the checklist they suggest: ask your own PM to build the reports, ask security to approve the access tier, and ask an engineer to explain the event and flag setup.
Public reviews overrepresent people motivated to post and may describe older packages or unusual implementations. Read them for useful failure modes, then ask your own PM to build the reports and verify identity, permissions, and costs in a small pilot.
Section 10Who should choose PostHog, and who should pause
Choose PostHog for a serious pilot if one product team owns an instrumentable web or app flow, has an engineer who can keep event and flag definitions tidy, and routinely needs to move from a behavioral chart to a replay or controlled rollout. It is especially plausible when the team currently loses time copying identifiers and cohorts among separate systems. A pilot should include the actual PM who will live in reports, not only the engineer who can make a demo work.
Pause if the team cannot answer who is allowed to see recordings, where sensitive data may appear, or how an account is identified across devices. Those are preconditions for trustworthy analysis. Also pause if security requires a specific SSO, role, region, or retention arrangement that procurement has not confirmed. Public product pages show options; they do not show whether your required control is included in the affordable tier. A team seeking only simple website traffic or only one mature specialist workflow should price that narrower job before funding a platform migration.
If the existing warehouse is the official source for revenue and customer status, keep that governance intact during evaluation. PostHog can still be the place where product managers explore a funnel and inspect sessions. If the existing experiment platform already has carefully audited exposure and guardrails, replacing it needs a stronger reason than fewer vendors on a slide. The proper comparison is the time and error rate of the team’s real decision loop, plus its total operating cost.
Section 11A two-week pilot that can produce a real decision
First, prove the data contract
Select one high-value path, such as signup to first project creation. Write the exact success event, account and person IDs, eligibility rules, conversion window, and exclusion rules in a short spec. Our activation rate calculator helps make the numerator and denominator explicit once those choices are settled. Instrument named events from the application for each business step, then use autocapture only to explore the interactions between those steps. Compare a handful of raw events with backend records. Fix duplicates, missing IDs, and time-zone mistakes before opening a dashboard for stakeholders.
Next, prove the replay and release handoff
For a consenting test user, confirm that a funnel segment leads to the right session and that sensitive information is masked on every relevant screen. Let the intended PM find a stalled session without an engineer narrating. Have security inspect access and retention. Put a harmless interface change behind a flag, verify the default state, target a small internal group, and rehearse rollback. Record whether the actual exposure event matches the flag state the user saw.
Then, price and decide
Create one experiment with a prespecified outcome and a guardrail, but do not infer a business effect from a tiny pilot. The acceptance criterion is that assignment, exposure, outcome, and report filters agree. Connect one business data source or query one exported table, reconcile selected rows with its source, and record sync delay. Pull a week of each usage meter into a normal and peak monthly forecast. At the end, ask the PM, engineer, analyst, privacy owner, and budget owner to sign off on their parts. If any cannot, write the failing condition and repair it before broad rollout.
The verdict is conditional. PostHog’s connected design can make the product loop shorter because diagnosis, recordings, release targeting, experiments, and data context share a home. It can also concentrate the consequences of one poor data definition. A technically supported team with clear ownership has a credible reason to pilot it. The team that needs a finished answer from an unplanned event stream should solve its measurement contract first. That is what makes the platform decision safe enough to revisit after two weeks.