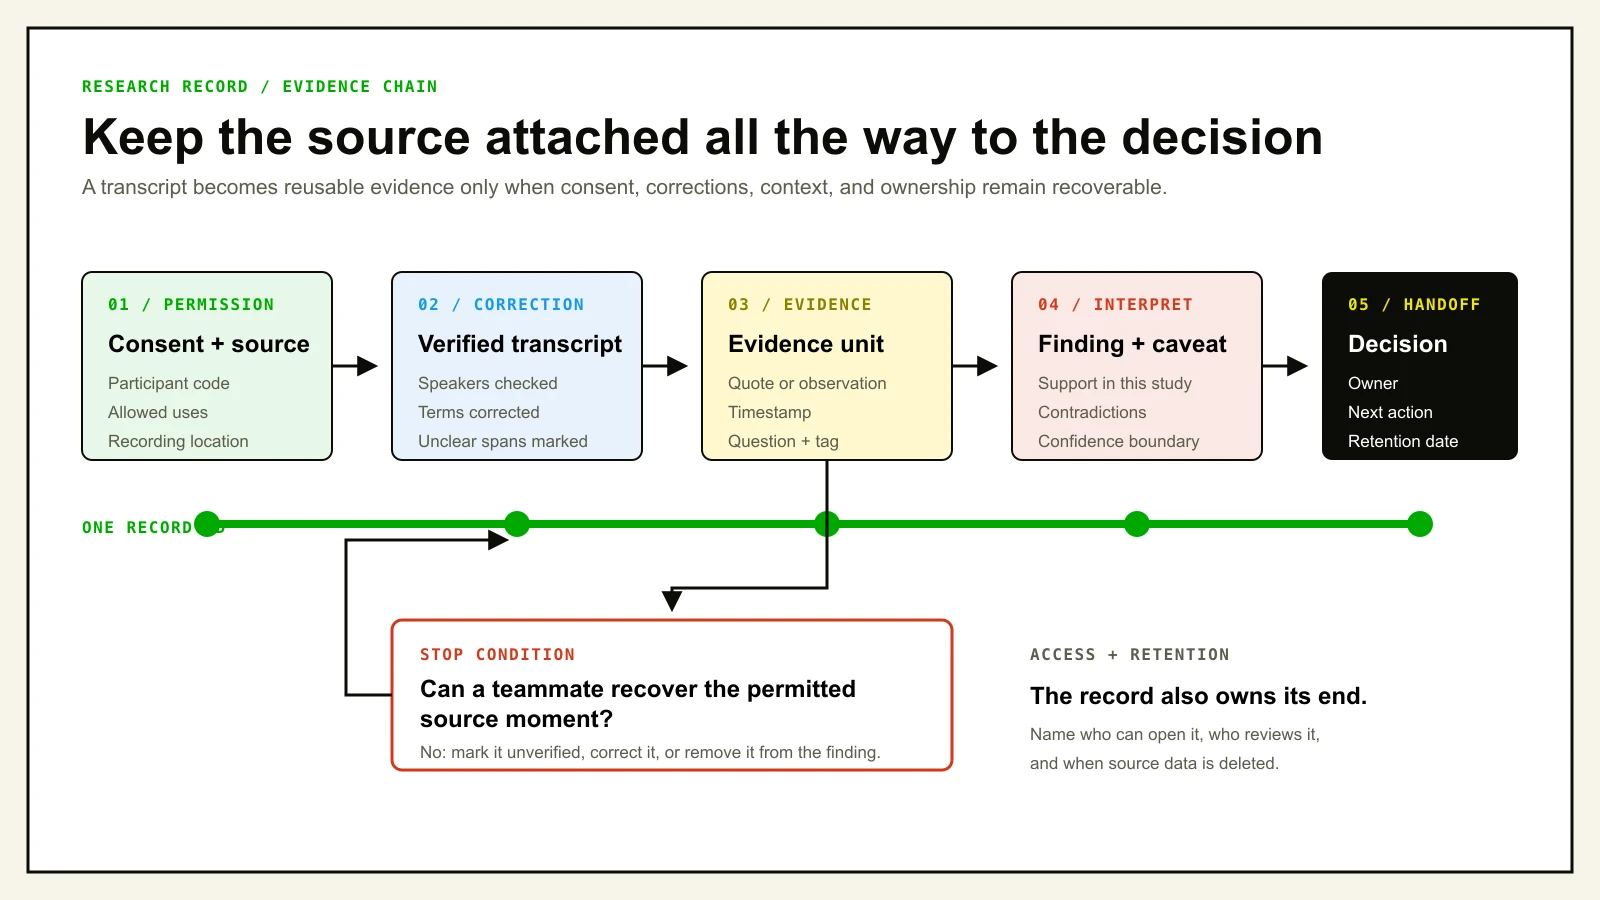
The useful question is not which AI transcription tool produces the prettiest first draft. It is what happens after a user interview when somebody needs to find the moment, check the wording, connect it to a theme, and show the underlying evidence to a teammate who was not in the room. A transcript that cannot survive those steps is still a pile of text.
That changes how to choose. One team needs a research repository that turns recordings into tagged evidence. Another needs a fast clip from a pricing interview. A third needs live notes while the conversation is happening. Sometimes the right answer is to pay for a human to review a quote before it appears in a report. These are different jobs, and they reward different tools.
These five tools serve different post-interview jobs. None is a universal accuracy winner: transcript quality depends on language, microphone quality, overlapping speech, accents, domain terms, speaker labels, timecodes, and the effort needed to correct errors. Treat every generated transcript as a starting point, especially when a participant’s exact words influence a roadmap or a public claim.
Section 011. Dovetail: best when the transcript needs to become a research asset
- Pros: Transcripts flow into a shared research repository with tags and themes.
- Cons: A useful repository needs an agreed taxonomy and team adoption.
Dovetail is the strongest fit here when transcription is only the entrance to a broader research system. Its documentation says a project can accept audio or video from interviews and usability tests, generate a transcript, then turn highlighted passages into tagged, searchable clips. That gives the team a useful chain: raw session, selected evidence, theme, and reported insight. A researcher who needs to answer “where did this finding come from?” has a clearer route than with a standalone recorder.
The product's AI guidance also matters. Dovetail says it marks AI contributions in workspace material and describes chat answers as traceable to source data. That does not make a generated synthesis correct. It does give a reviewer a practical place to start checking it. The safer habit is to ask the tool for a narrow question, open the supporting evidence, then decide whether the interpretation belongs in a readout. A broad request for “top insights” is faster, but it can flatten exceptions that are valuable in qualitative work.
Choose Dovetail if several researchers or product partners need to return to the same body of interviews over time. Do not choose it merely because it can transcribe. It works best when the team maintains a modest codebook, names studies consistently, and decides what counts as an insight versus an unverified suggestion. One public UXResearch discussion found the transcription and tagging useful but called data export a deal breaker. That is a reminder to test export, permissions, retention, and portability with your actual study materials before a large migration.
A practical Dovetail trial starts with a bounded research question, not a bulk import. Load four to six consented interviews from one study. Give two researchers the same initial codebook, then compare where they tag the same passage differently. Ask a stakeholder to open a final finding and trace it back to the recording without help. That small exercise reveals whether the workspace is serving research or simply storing transcripts. It also exposes decisions that are easy to postpone, such as whether a quote can carry several tags, how to separate participant facts from researcher interpretation, and who can change a shared taxonomy. The platform can make evidence easier to revisit, but it cannot decide which themes are meaningful. Make the human review step visible in the project workflow. That is the guardrail against a polished AI summary becoming a conclusion before the team has inspected the underlying sessions.
Section 022. Grain: best for capture, clips, and a fast research handoff
- Pros: Capture and clips make interview evidence easy to share.
- Cons: Paid recording seats add cost, and cross-study structure remains a team task.
Grain fits the moment when a researcher is still in the interview and wants to preserve what matters before the session disappears into a folder. Its interview-transcription guide describes real-time transcription for recorded calls, editable speaker labels after an upload, and the ability to make highlights while the conversation is happening. That workflow is especially useful for a product team that needs a short clip or an evidence-backed follow-up while the participant's context is still fresh.
The practical advantage is not that an AI summary can replace a debrief. It is that an interviewer can mark a surprising statement, return to it with the full recording, and send the relevant moment to a designer or product manager. Grain's pricing material distinguishes paid seats that can record, upload, and import from free viewers who can view and collaborate on shared work. That distinction can make stakeholder access cheaper, but it also means a trial should model who will create the record and who will only consume it.
Choose Grain when clips and lightweight evidence sharing are the immediate bottleneck. It is less compelling when your central problem is keeping an organization-wide taxonomy across dozens of studies, in which case a dedicated repository can be the better first purchase. Watch the plan boundaries around uploads, recorder seats, and advanced AI actions. Also run a short pilot with a consented recording that includes the language, audio quality, and speaker pattern you expect in real research. Correct the speaker labels before you judge the rest of the workflow.
The clip is the unit of work to test with Grain. After each interview, ask the moderator to create two clips: one that supports the working hypothesis and one that complicates it. Send both to a product partner with the question that elicited the response. If the partner can understand the context and ask a useful follow-up, the handoff is doing its job. If the clip travels without the question, participant details, or a clear link to the full recording, it may become an attractive but misleading anecdote. This is where a small naming convention helps. Include the study name, participant segment, date, question area, and correction status in the shared record. Grain can make the evidence portable, but the research team decides how portable it should be. Teams that only collect highlights often discover later that they cannot tell whether the quoted moment was typical, exceptional, or prompted by the interviewer.
Section 033. Otter.ai: best for a low-commitment live-transcription pilot
- Pros: Live transcription and searchable notes offer an easy starting point.
- Cons: Usage caps and limited research governance constrain larger studies.
Otter.ai is a sensible starting point for a team that wants to change one habit first: stop trying to take a full set of notes while moderating an interview. Its current pricing page lists live transcription, speaker identification, playback, and AI Chat, alongside a Basic plan with 300 transcription minutes each month. Those are enough ingredients for a researcher to record a small set of calls, revisit a phrase, correct a speaker, and see whether the team actually returns to the record later.
An independent Harvard Business School guide, written before the current product surface, described Otter as useful with Zoom, easy to edit, and capable of multiple export formats. Treat that as workflow context, not a current benchmark. The more useful decision test is local: can your team reliably identify the participant, correct product names, find the source of a theme, and retain the material according to its study policy? If the answer is no, more summaries will not fix the research process.
Otter is best as a focused pilot or as the live-capture layer inside an already-defined research process. Its limits matter as the habit grows. The free plan's minutes and session boundaries can be enough for a discovery sprint but not a sustained program, and its file-import allowance can matter for interviews recorded elsewhere. If the pilot works, decide whether Otter remains the searchable meeting layer or whether the approved transcript needs to move into a repository where studies, participant metadata, permissions, and coding live together.
A careful Otter pilot should resist the urge to judge the product on summary quality alone. Give the team a retrieval drill instead. One person writes a one-sentence finding and names the participant segment but does not include a timecode. Another person has five minutes to find the relevant moment, listen back, and decide whether the finding is faithful to the exchange. Repeat the exercise after a few calls. If it remains easy, the searchable record is helping. If the team repeatedly fixes speaker labels, loses question context, or cannot find the source, that is signal too. The solution may be a different setting, a different tool, or a stronger operating practice. Tool selection and research discipline are related. A generous free tier is valuable when it lets you discover that distinction before a procurement decision.
Section 044. Rev: best when a quote needs a human-review option
- Pros: Human transcription is available when an AI draft needs extra checking.
- Cons: Human verification costs more and takes longer than the AI path.
Rev belongs in this roundup for a different reason from the research repositories and meeting recorders. It gives a team a choice between a fast AI transcript and a paid human-transcription path. Rev's current help center lists AI transcription at $0.25 per audio minute and human transcription starting at $1.99 per minute. Its pricing page describes the human service as 99%+ accurate and delivered within 12 hours or less. Those are Rev's published terms, not a universal guarantee for a particular interview.
The distinction is useful when the exact wording carries unusual weight. Consider a research participant's quote that will appear in a board packet, customer story, regulatory review, or sensitive product decision. An AI draft can still save time by making the recording searchable. But the team can buy a human review for the material that needs a more accountable record, instead of silently treating every machine-generated sentence as final. That is a procurement and risk decision, not a claim that researchers should outsource all sense-making.
Choose Rev if you need this escalation path and are comfortable keeping analysis somewhere else. It is not a substitute for a research repository, consent process, or a study codebook. Build the handoff explicitly: retain the audio and timecodes, request the transcript level the study needs, resolve the final speaker names, and store the approved version beside the notes that interpret it. The extra cost is easiest to justify when the team has already named which interviews or quotations need that level of care.
The important operational choice is to define that escalation before the interview round starts. A team can decide that routine exploratory calls receive an AI transcript and moderator review, while a small set of executive interviews or evidence used outside the company receives human transcription. That prevents a rushed researcher from improvising a standard once a memorable quote appears. It also makes budgeting more honest. Rev's per-minute structure maps clearly to a set of recordings, but a human-verified transcript still needs the researcher's context. A transcriber can preserve words; they cannot decide why an answer mattered, whether a pause changed the meaning, or how a participant's view compares with others. Keep the approved transcript linked to the original media, the interview guide, and the analysis notes. Then the additional verification has a defined role instead of becoming a costly duplicate of the research process.
Section 055. Descript: best when the transcript is the edit decision
- Pros: Transcript-led editing turns interview moments into polished media evidence.
- Cons: Production features may exceed a simple transcription need.
Descript is the outlier in a useful way. It is not the first choice for maintaining a research library. It is a strong candidate when an interview transcript must turn into an edited piece of evidence: a customer-story excerpt, a stakeholder playback, a short concept-test reel, or a clip that lets a team hear the participant rather than only read a paraphrase. Its pricing page lists transcription in 25 languages and ties capacity to media hours, while its product positioning centers text-based media editing.
That changes the work after transcription. Instead of treating the transcript as the last artifact, the researcher can use it to decide which section of audio or video deserves to be shown. A historical Harvard Business School guide also described Descript as easy to edit through the document and noted export options. Again, that is not an accuracy benchmark. It is a reason to test whether the edit interface helps your team preserve context, rather than extracting a polished line that loses the question that prompted it.
Choose Descript when media editing is the critical handoff. Do not buy it expecting a cross-study system for participant metadata, themes, study governance, and research operations. A small team can pair it with a simple, disciplined repository or document process: keep the source recording, make a transcript correction log, save the final clip with its question and participant context, and link it back to the study finding. The media artifact can make research more legible, but it should not become the only surviving evidence.
Descript is particularly useful when the team has already learned that a written quote alone does not change minds. Hearing hesitation, delight, confusion, or a participant's sequence of thought can preserve texture that a clean transcript removes. That strength has a matching risk. An edited moment can overstate a pattern if the viewer cannot see the question, the surrounding conversation, and the number of participants who expressed a similar view. Set a simple editorial rule: every clip in a research readout gets a source link, a label for the study and segment, and a short note saying whether it illustrates a broader theme or an exception worth investigating. The transcript-led edit can then make a real research finding easier to understand, rather than turning an isolated moment into evidence of product-market fit.